OpenAI and Broadcom Collaborate to Introduce Advanced LLM-Optimized Intelligence Processor
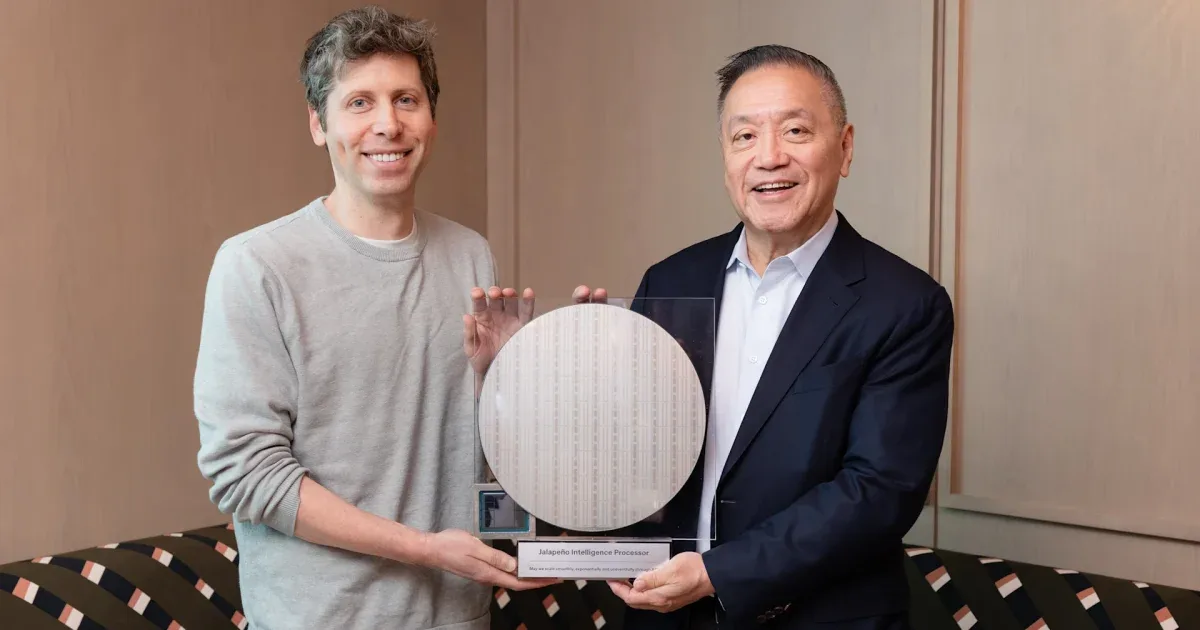
In a significant stride for artificial intelligence, OpenAI and Broadcom have announced their collaboration on a cutting-edge intelligence processor meticulously engineered for Large Language Models (LLMs). Unveiled as "Jalapeño," this new chip is OpenAI's first custom-designed accelerator, developed in partnership with Broadcom to optimize LLM inference workloads. This strategic partnership addresses the critical need for specialized hardware capable of efficiently handling the immense computational demands of advanced AI models. The Jalapeño processor promises substantial improvements in the speed and energy efficiency of LLM operations, aiming to deliver performance per watt substantially better than current state-of-the-art accelerators. By moving beyond general-purpose computing units, this dedicated architecture is expected to drastically reduce the latency associated with processing complex AI queries and enhance the scalability of AI applications, thereby making advanced AI faster, more reliable, and more accessible.
The implications of this development are far-reaching. Optimized hardware for LLMs means that developers can deploy larger, more sophisticated models faster and with greater cost-effectiveness, potentially lowering "token costs" for businesses. This could lead to breakthroughs in areas such as natural language understanding, content generation, and intelligent automation across various industries. For businesses, it translates into faster insights, more responsive AI assistants, and the ability to integrate advanced AI capabilities into their products and services with unprecedented ease. This collaboration underscores a growing trend in the AI industry towards vertical integration, where software innovation (like OpenAI's models) is increasingly paired with bespoke hardware solutions to unlock the next generation of AI performance and to control the full stack of AI development.